Three weeks after the Astra and Fable drops, Anthropic, OpenAI, and Xiaomi dumped new models on the exact same Tuesday.
Anthropic dropped Claude Opus 5.5. OpenAI dropped GPT-6 Sol and GPT-6 Luna. Xiaomi dropped MiMo-V2.6-Pro.
Anthropic
- Claude Opus 5.5 (Sept 22)
OpenAI
- GPT-6 Sol (Sept 22)
- GPT-6 Luna (Sept 22)
Xiaomi
- MiMo-V2.6-Pro (Sept 22)
Both labs are shifting away from flexing pure intelligence ceilings to price-cutting their workhorses. Anthropic claims Opus 5.5 runs at Fable 5.1 capability at 40% lower cost. OpenAI cut GPT-6 Sol and Luna API prices 50% below GPT-5.6.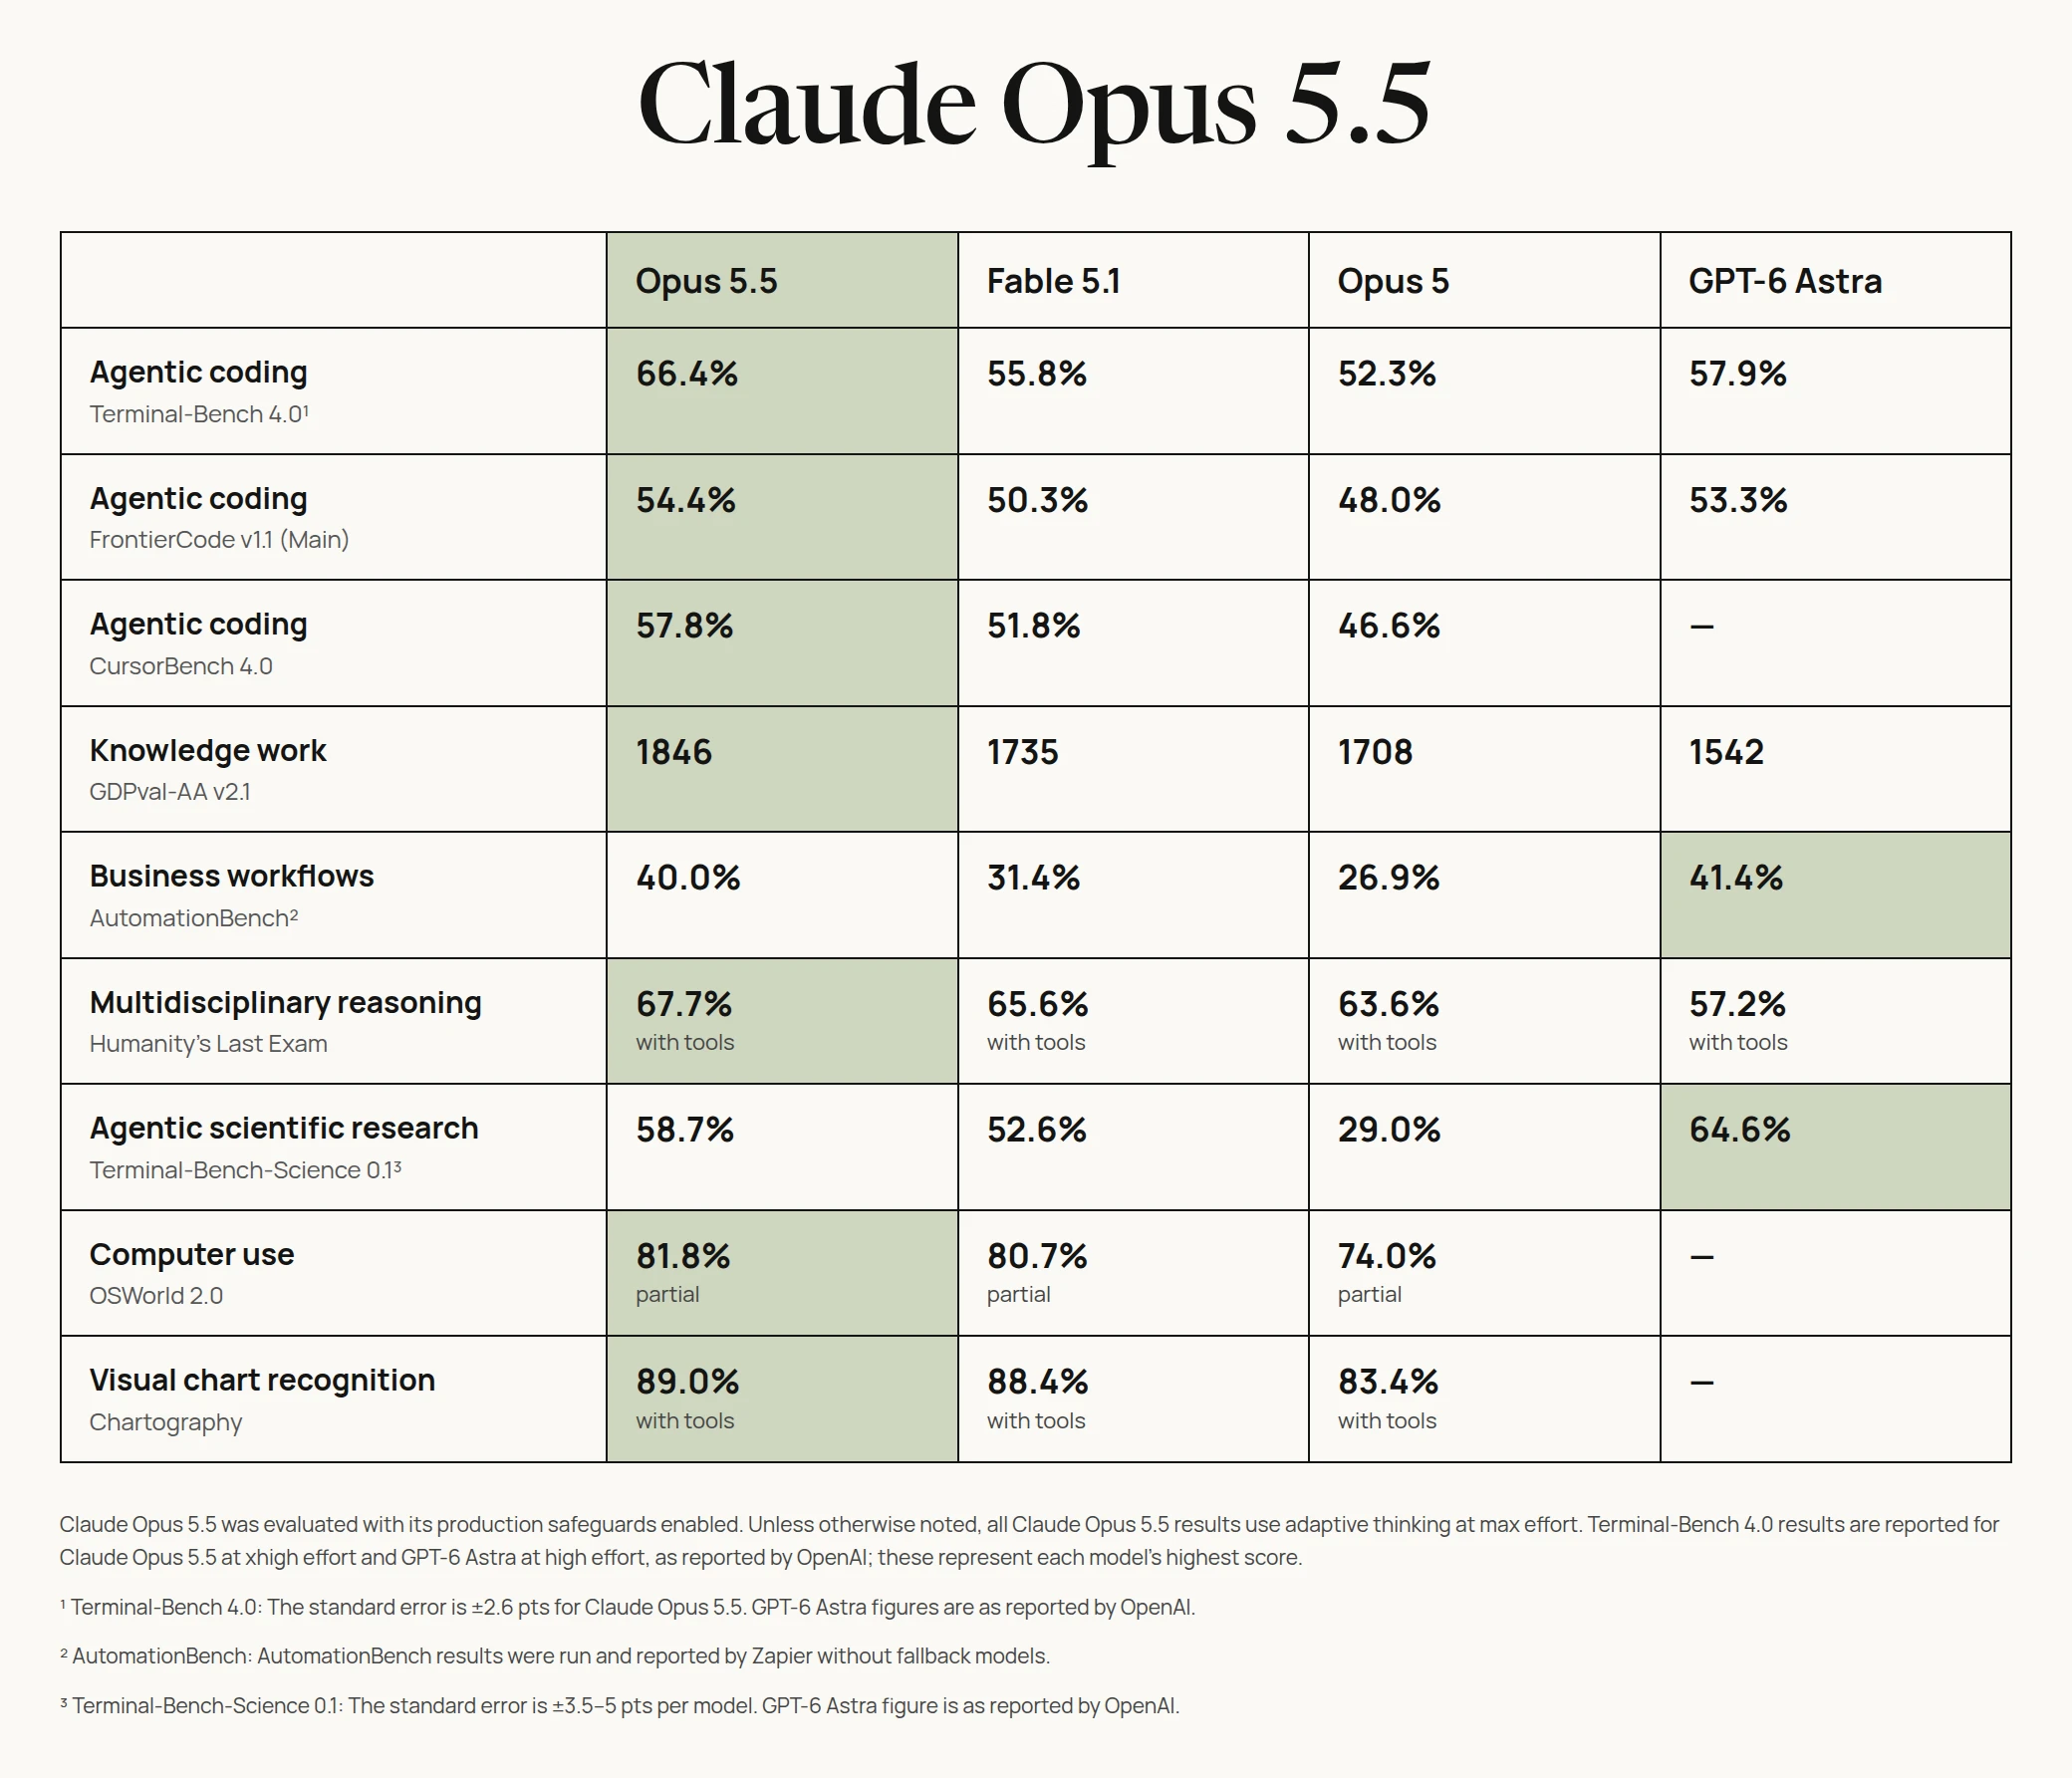
The Numbers (Anthropic)
Agentic coding (Terminal-Bench 4.0) 66.4%. +15% over GPT-6 Astra (57.9%) and +19% over Fable 5.1 (55.8%). That takes back the terminal lead Anthropic lost two weeks ago.
Agentic coding (FrontierCode v1.1) 54.4%. Edges out Astra (53.3%) and +8% over Fable 5.1.
Knowledge work (GDPval-AA v2.1) 1846 Elo. +111 over Fable 5.1 and +304 over Astra (1542). Clear win.
Business workflows (AutomationBench) 40.0%. Astra still holds the top spot at 41.4%, but this is +27% over Fable 5.1.
Reasoning (Humanity's Last Exam) 67.7% with tools. +18% over Astra (57.2%).
Agentic scientific research (Terminal-Bench-Science 0.1) 58.7%. 2.0x Opus 5 (29.0%), though Astra still leads at 64.6%.
Computer use (OSWorld 2.0) 81.8% partial. Up from 80.7% on Fable 5.1.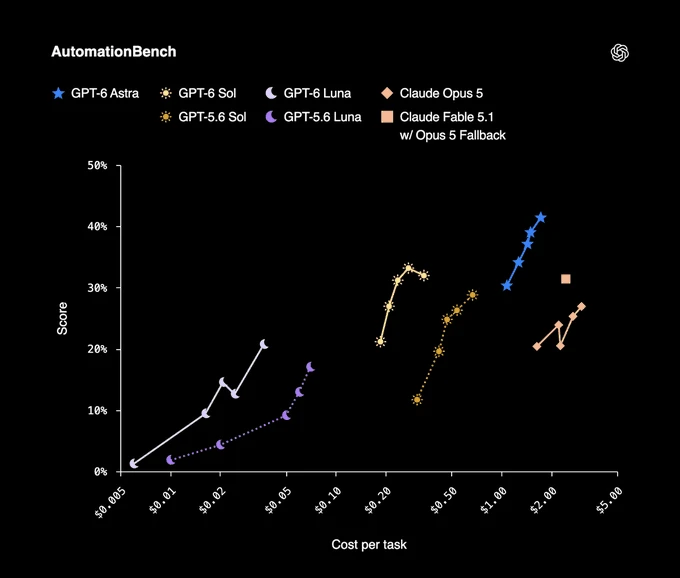
The Numbers (OpenAI)
OpenAI's playbook here is cost per task.
Business workflows (AutomationBench) 33.2% on Sol at xhigh effort. Beats Opus 5 (26.9%) at roughly a fifth of the price ($0.30 vs $1.50+).
Long-horizon coding (DeepSWE v1.1) 68.8% on Sol at max effort. Right next to Fable 5.1 (69.9%) and Luna hits 66.6%.
Computer use (OSWorld 2.0) 60.5% on Sol. Ties Opus 5 at lower token cost.
Coding deception (Internal eval) 1.3% on Sol, down from 10.4% on GPT-5.6 Sol. Luna is 2.8%.
Pricing Check
Anthropic
- Opus 5.5: $4/M in, $20/M out. Cache reads down to $0.20/M.
OpenAI
- GPT-6 Sol: $2/M in, $10/M out.
- GPT-6 Luna: $0.10/M in, $0.50/M out.
Sol is half the price of Opus 5.5. Luna is basically free for high-frequency agent loops.
And Xiaomi's Open Weights
Xiaomi dropped MiMo-V2.6-Pro out of nowhere on the same day.
1.02T parameter sparse MoE (42B active), 1M context, full MIT license on Hugging Face.
Long-horizon coding (DeepSWE v1.1) 71.9%. Beats GPT-6 Sol (68.8%) and sits right under Claude Opus 5 (74.0%). For an open model that's wild.
Terminal-Bench 4.0 is only 34.9%, so it struggles on raw CLI tool harnesses, but open weights hitting 71.9% on DeepSWE under MIT is huge.
Thoughts
When models get slightly smarter, you do the same things a little better. When they get half as expensive, you build different things. You stop rationing calls and start running loops you couldn't justify before.
The gap between closed labs and open weights is down to a few weeks now.